
AI data labeling is the process of tagging raw images, text, audio, and video so a supervised machine learning model has ground truth to learn from. Model accuracy tracks label quality almost directly: sloppy labels produce sloppy predictions, no matter how sophisticated the architecture. Teams generally get labels through three routes: fully human annotation, automated or model-generated labeling, or a hybrid pipeline that uses human-in-the-loop review with active learning to catch what automation misses.
TL;DR:
- High-quality labeling requires clear instructions and a well-defined ontology to ensure consistency and accuracy across annotators.
- Automation and active learning significantly reduce costs by prioritizing uncertain samples for human review and routing routine tasks to models.
- Labeling for safety-critical applications, like autonomous vehicles or medical imaging, demands precision, often requiring stringent IoU thresholds or pixel-level segmentation.
- Incorporating continuous quality metrics such as inter-annotator agreement and model-based validation helps prevent label drift and maintains dataset reliability over time.
- Selecting a flexible, integrated labeling platform with multi-data support, governance features, and model-in-the-loop workflows is essential for scalable, cost-effective AI development.
Table of Contents
- How AI Data Labeling Works, Step by Step
- Common Label Types and Task Formats You'll Encounter
- In-House, Crowdsourced, Platform, or Programmatic: Choosing How to Source Labels
- Measuring Label Quality: Metrics, Auditing, and Governance
- Scaling Labeling Without Blowing the Budget
- What to Look for in a Labeling Platform
- Where Labeling Quality Makes or Breaks the Project
- How Requestum Approaches Labeling Projects for AI Clients
- Editor Note: The Shift Toward Data-Centric AI
- Sources
- FAQ
How AI Data Labeling Works, Step by Step
Every labeling project starts with a decision, not a dataset: what exactly counts as "correct"? That decision gets written down as an ontology and a set of instructions, and it shapes everything downstream. Teams that skip this step tend to discover, three thousand labeled samples later, that half their annotators interpreted "defect" differently than the other half.
Here's the operational sequence most labeling programs follow, whether they run on Label Studio, a managed cloud platform, or a custom internal tool:
- Define the ontology and write instructions. Specify every label class, edge case, and exception. Golden tasks (pre-solved examples with known correct answers) belong in the instructions, not buried in a wiki page nobody reads.
- Build task templates. Design the annotator interface around the actual task: bounding box tools for object detection, span highlighters for text, waveform viewers for audio events.
- Ingest data and populate queues. Raw files get chunked into individual tasks and routed to annotator pools, often with priority weighting so urgent or high-value samples surface first.
- Present prelabeled suggestions where available. Many platforms, including Azure Machine Learning's labeling tool, let a model generate a first-pass label that a human then accepts or corrects. Prelabeling coverage typically expands as the underlying model's confidence improves, which means early batches lean human and later batches lean machine-assisted.
- Correct, submit, and reconcile. Annotators fix what the model got wrong, flag ambiguous cases for review, and submit. Disagreements get routed to a senior reviewer or adjudicator.
- Export and hand off. Finished labels get exported into formats the training pipeline expects (COCO JSON, YOLO text files, CoNLL for NER) and versioned alongside the raw data.
- Iterate. Model performance on a validation set often reveals labeling gaps that weren't visible during annotation. Those gaps get folded back into revised instructions, and the cycle repeats.
The step people underestimate is step one. A vague ontology doesn't just slow annotators down. It manufactures inconsistent ground truth that no amount of downstream QA can fully repair.
Common Label Types and Task Formats You'll Encounter
Different data types demand different labeling mechanics, and the format you choose determines what artifact your model actually trains on.
Image labeling covers the widest range of task types:
- Classification assigns a single tag to the whole image (cat, dog, defective part).
- Bounding boxes draw rectangles around objects for detection tasks, the backbone of most autonomous vehicle and retail computer vision projects.
- Semantic segmentation colors every pixel by class, producing a mask rather than a box, which is essential when object boundaries matter (a tumor's exact edge, a road's curb line).
- Instance segmentation goes further, distinguishing between multiple objects of the same class in one frame.
- Keypoint labeling marks specific points, like joints on a human body for pose estimation.
Video labeling inherits image techniques but adds a continuity problem: a bounding box has to track the same object across hundreds of frames without drifting or flickering, and action recognition requires labeling a temporal span rather than a single moment. This is where labeling density and consistency requirements climb sharply compared to static images.
Text labeling ranges from simple classification (spam or not spam) to multi-label tagging (a support ticket touching billing and shipping at once) to named entity recognition, where annotators tag spans of text as a person, organization, date, or product. Sequence labeling, used heavily in tasks like part-of-speech tagging, assigns a label to every token rather than the whole document.
Audio and time-series labeling includes transcription, event tagging (marking where a dog barks in a security recording), and sensor annotation, where a stream of numeric readings gets labeled with the state it represents, like a machine transitioning from normal operation to fault.
A quick example of what each produces: an image classification task hands the training pipeline a single label per file, while a segmentation task hands it a pixel mask array the same dimensions as the source image. Those are very different inputs for a model, even though both started as "labeling."
In-House, Crowdsourced, Platform, or Programmatic: Choosing How to Source Labels
The sourcing decision usually comes down to three constraints: how sensitive the data is, how specialized the labeling task is, and how fast the project needs to scale.
- In-house teams work best for regulated or proprietary data (medical records, financial documents) and for tasks that require deep domain judgment no outside annotator could reasonably develop quickly.
- Crowdsourced labeling wins on speed and cost for high-volume, low-complexity tasks like basic image classification, but consistency drops without strong instructions and consensus checks.
- Managed platform vendors, such as SageMaker Ground Truth, bundle workflow tooling with access to a labeler pool, which shortens the time between "we have raw data" and "we have a labeled batch" without building infrastructure from scratch.
- Synthetic and programmatic labeling generates labels algorithmically, either through simulation (rendering synthetic scenes with known ground truth) or weak supervision rules. It scales cheaply once built but carries real compute costs upfront and can bake in systematic bias if the generation logic doesn't match real-world distribution.
Most mature programs don't pick one lane. They route routine, high-volume samples to crowdsourcing or automation and reserve in-house experts for the ambiguous, high-stakes fraction of the dataset, an orchestration pattern that mirrors how meta-controller systems route tasks between specialized models and human reviewers to cut cost without sacrificing accuracy.
Pro Tip: Before scaling any sourcing approach, run a 200 to 500 sample pilot through it and measure agreement against an expert-labeled gold set. A sourcing strategy that looks cheap on paper often gets expensive fast once rework costs are counted in.
Measuring Label Quality: Metrics, Auditing, and Governance
Label quality isn't a one-time check. It's a continuous measurement problem, and teams that treat it as a final QA pass rather than an ongoing process tend to discover accuracy issues only after the model is already in production.
Four signals form the backbone of most quality programs:
- Inter-annotator agreement (IAA). Multiple annotators label the same sample independently, and their agreement rate reveals whether the ontology is clear enough to produce consistent results. Low IAA on a specific label class usually means the instructions for that class need rewriting, not that the annotators need retraining.
- Consensus scoring. For ambiguous cases, majority vote (or weighted vote, if some annotators have higher historical accuracy) settles the final label rather than relying on any single person's judgment.
- Benchmark and hidden test tasks. Seeding the queue with pre-solved gold examples lets teams screen annotator accuracy continuously without a separate audit cycle.
- Model-based validation. Tracking how model performance shifts after a relabeling pass is one of the more reliable signals for whether the original labels were actually the bottleneck. Combining consensus, benchmarking, and auditing tends to catch quality issues that any single metric misses.
Where teams get burned: label drift. A model trained on last year's labeling standards can quietly degrade if the world it's describing shifts (new product categories, new fraud patterns, new medical terminology) while the label ontology stays frozen. Versioning both the data and the ontology, and tying each training run to a specific label schema version, is what makes a labeling program auditable months later when someone asks "why did accuracy drop in March?"
Bounding box and segmentation tasks add one more layer: measuring overlap between annotator output and ground truth using intersection over union (IoU), typically flagging anything below a set threshold for review rather than trusting visual inspection alone.
Scaling Labeling Without Blowing the Budget
Throughput and accuracy pull in opposite directions unless automation is doing real work in the pipeline, not just window dressing on a dashboard.
Active learning flips the usual "label everything" approach on its head. Instead of annotating a dataset uniformly, the model flags the samples it's least confident about, and those uncertain examples get prioritized for human labeling while the model already handles the easy majority correctly. This concentrates human effort exactly where it produces the most learning value per label.
Prelabeling works alongside active learning rather than replacing it. A model proposes labels, and confidence thresholds decide the workflow: high-confidence predictions get a light human confirmation pass, low-confidence ones get a full manual review, and the threshold shifts as the model improves over time.
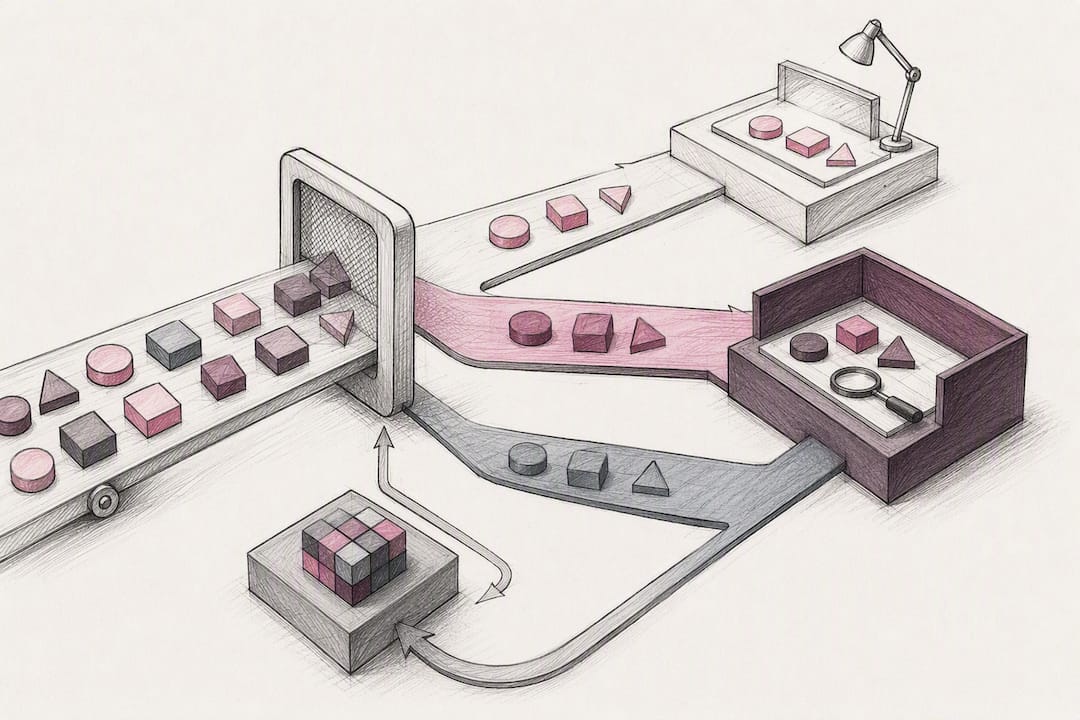
Multi-model orchestration is the newer pattern worth watching. Rather than sending every annotation task to one large, expensive model, a meta-controller routes routine, high-volume categories to smaller specialized models and reserves ambiguous or high-cost categories for human experts, cutting API spend while improving overall accuracy compared to a single-model approach. The specialist models then get periodically fine-tuned on the hard cases the meta-controller flagged, creating a feedback loop that gets sharper over time.
Automation earns its place when the task is repetitive and the error cost is low. It has no business handling nuanced judgment calls (sarcasm detection, subtle medical findings, safety-critical edge cases) without a human check behind it, since automated annotation still struggles with fine-grained semantics that don't fit clean rules.
- Route high-confidence, repetitive tasks to automation first.
- Keep humans on anything involving ambiguity, rarity, or safety consequences.
- Recalculate ROI whenever labeling volume changes by an order of magnitude, since the cheapest approach at 10,000 samples is rarely the cheapest at 10 million.
Pro Tip: Track cost per usable label, not cost per label submitted. A cheap automated label that triggers a full human rework cycle later is more expensive than an honest human label upfront.
What to Look for in a Labeling Platform
Picking labeling tooling is less about brand names and more about whether the platform actually supports the workflow a project needs six months from now, not just the pilot batch.
- Multi-data-type support and a customizable interface. A platform that only handles images poorly serves a team that will eventually need text and audio too. Open-source options like Label Studio support images, audio, text, and video through configurable interfaces, which is useful when project scope tends to expand.
- Built-in quality and governance tooling. Consensus scoring, benchmark task support, and audit trails should be native features, not something bolted on with spreadsheets.
- Model-in-the-loop and active learning support. Prelabeling APIs and an accessible endpoint for feeding model predictions back into the annotation queue matter once volume grows past what pure human labeling can sustain.
- Operational integrations. Cloud storage connectors (S3, GCS), CI/CD hooks, dataset versioning, and role-based access control (RBAC) determine whether labeling fits into an existing engineering pipeline or sits awkwardly outside it.
- Security and compliance controls. Sensitive domains (health data, financial records) need encryption at rest, audit logging, and access controls that meet the relevant regulatory bar before a single sample gets uploaded.
| Capability | Why it matters | Example source |
|---|---|---|
| Multi-type annotation UI | Supports images, text, audio, video without switching tools | Label Studio |
| Managed human labeler access | Speeds project start without building a labeler pool from scratch | SageMaker Ground Truth |
| Assisted/prelabeling workflow | Model suggests labels; humans correct and confirm | Azure ML labeling |
For teams that want a hands-on look at how image annotation interfaces actually behave, AmmarAI's image labeling demo walks through a practical example of how visual question-answering and labeling workflows connect.
Where Labeling Quality Makes or Breaks the Project
Autonomous systems and video tracking demand dense, frame-consistent bounding boxes, and teams typically hold IoU thresholds above 0.7 for anything safety-relevant, since a drifting box on a pedestrian detection model isn't a rounding error, it's a missed detection.
Medical imaging usually requires credentialed experts drawing pixel-level segmentation masks, because a bounding box around "the abnormality" doesn't give a diagnostic model the boundary precision it needs to be clinically useful.
NLP and large language model projects increasingly rely on preference data (ranking which of two model responses is better) alongside classic named entity recognition, since instruction-tuning pipelines need both correctness labels and comparative judgment data.
Industrial defect detection and time-series anomaly labeling hinge on catching rare events in mostly normal data, which makes active learning particularly valuable since the interesting samples are a small fraction of the total.
A workable project plan usually looks like this: define dataset size and label schema in week one, run a pilot batch with dual annotation for IAA measurement in week two, open QA gates and benchmark tasks in week three, then scale to full volume once agreement holds above target for two consecutive batches.
How Requestum Approaches Labeling Projects for AI Clients
Labeling work rarely exists in isolation. It's one stage of a larger AI build, and treating it that way from the start avoids the rework that happens when labeling decisions get made without the training pipeline in mind. Requestum's AI and data science engagements typically follow a discovery phase (understanding the model's actual decision boundary and edge cases), a labeling plan (ontology, tooling, sourcing mix), a QA phase (consensus checks, benchmark tasks), and a handoff into model training with full data versioning intact.
That sequencing matters because labeling decisions made in isolation from the model's actual failure modes tend to produce technically correct but practically useless datasets. Teams evaluating a development partner for data science and machine learning work should ask specifically how the labeling plan connects to model validation, not just how many annotators are available.
Editor Note: The Shift Toward Data-Centric AI
Model architecture has become commoditized. What separates a good model from a mediocre one is increasingly the dataset underneath it, and that's the core argument for data-centric AI. Hybrid pipelines, human judgment paired with active learning and prelabeling, consistently outperform either pure-human or pure-automated approaches on both cost and accuracy. Governance isn't optional overhead here; it's what makes a labeling program improve over time instead of decaying quietly. Teams weighing a custom build should treat labeling as infrastructure worth getting a dedicated development partner's input on, not a task to outsource and forget.
— Dmitry
Sources
FAQ
Does Data Annotation Really Pay You?
Yes. Companies and platforms pay individuals to label images, text, and audio for AI training, though pay scales with task complexity, from simple classification to specialized domain annotation requiring expert judgment.
Which AI Data Labeling Approaches Work Best for Teams?
There's no single best approach. Managed platforms like SageMaker Ground Truth suit teams wanting fast setup, open-source tools like Label Studio suit teams wanting full customization, and hybrid human-plus-automation pipelines suit teams scaling past what manual labeling alone can sustain.
What Is an AI Data Labeling Job?
An AI data labeling job involves tagging raw data, such as drawing bounding boxes on images, transcribing audio, or marking named entities in text, so a machine learning model has correctly labeled examples to learn from.
Can You Give an Example of Data Labeling?
A common example is drawing a bounding box around every car in a street photo and tagging each box "car," which gives an object detection model the ground truth it needs to learn what a car looks like in context.